
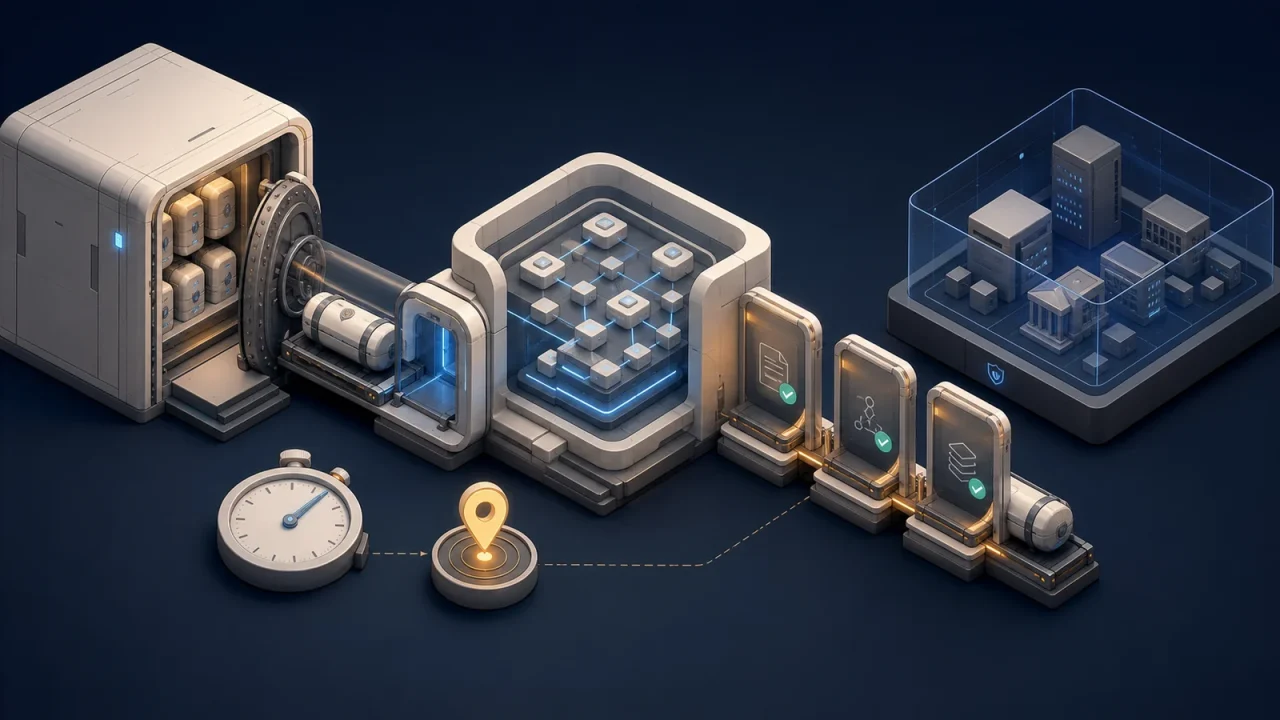
A successful database backup job does not prove that the application can recover. Database backup testing must restore real recovery points into an isolated environment, verify database and application consistency, measure elapsed time, and show that an operator can complete the procedure with the access and documentation available during an incident.
A backup is an input to recovery. A tested, usable restore is the result the business needs.
Checksums, green dashboards, and retained snapshots are useful evidence, but they do not prove that the right data can be restored within the time the business expects.
Database backup testing starts with recovery objectives
Define the recovery point objective: how much recent data the business can lose. Define the recovery time objective: how long the service can remain unavailable. Then identify the transactions, records, and application functions that prove recovery is complete.
A nightly backup cannot satisfy a one-hour recovery point. A restore that finishes in twenty minutes may still miss the recovery-time target if configuration, credentials, DNS, queues, and application validation require another four hours.
The University of Toronto’s backup-testing practices connect backup configuration to RPO and RTO and recommend testing database consistency and older restore points. The useful principle is to test against business objectives, not only tool completion.
Inventory every dependency needed for restore
Record the database engine and version, extensions, encryption keys, backup format, storage location, retention, service accounts, network access, restore commands, schema migrations, application release, and configuration needed to use the data.
Database engines support different backup methods. PostgreSQL documentation, for example, distinguishes SQL dumps, file-system backups, and continuous archiving. The restore procedure and point-in-time capabilities depend on the method chosen.
Keep recovery instructions available outside the failed system. A runbook stored only in the application database is unavailable when it is most needed.
Verify integrity, then perform a real restore
An integrity command can detect a damaged or incomplete backup artifact, but it is not a substitute for restoring it. MySQL Enterprise Backup documents a validate command for backup-image integrity. That check is useful and product-specific; the recovery test must still create a working database.
Restore into an isolated environment with no production write access. Use the same engine version and relevant extensions unless the test is deliberately proving a version migration. Capture start time, end time, errors, manual steps, and storage or compute requirements.
Validate application meaning, not just row counts
A database can start successfully while the application remains unusable. Run engine consistency checks, then verify schema versions, required tables, constraints, relationships, recent transactions, attachments or object references, search indexes, and background-job state.
Use business-level checks: open a recent customer record, reproduce an invoice total, authenticate a test account, load a report, and complete a read-only critical journey. Compare expected values captured before backup with the restored result.
Do not connect restored jobs, email, payments, webhooks, or scheduled tasks to production services. Recovery testing should prove the application without repeating real-world actions.
Test more than the newest backup
The newest recovery point covers only one failure scenario. Test an older retained backup, a point-in-time restore before a damaging transaction, a backup from another storage location, and recovery when the normal administrator is unavailable.
If backups are encrypted, prove that the required keys and permissions can be retrieved through the documented emergency process. If recovery depends on a vendor account, verify ownership, multifactor access, billing state, and support contacts.
Include partial-recovery scenarios too. An operator may need one accidentally deleted record, one tenant, one table, or a database state immediately before a faulty import rather than a complete environment replacement. Document whether the backup method supports that recovery and how restored data can be compared and safely reintroduced without overwriting newer legitimate work.
Schedule tests according to change and consequence
A rapidly changing transactional database needs more frequent evidence than a stable archive. Trigger additional tests after database-engine upgrades, extension changes, encryption-key rotation, major schema migrations, backup-tool changes, storage moves, and significant application releases.
Rotate scenarios rather than restoring the same newest backup every time. A monthly automated restore can prove the routine path, while quarterly operator exercises test older points, alternate locations, missing access, and application recovery. The schedule should cover the failure modes the business actually cannot tolerate.
Automate repeatable evidence
Automate isolated restore creation, integrity checks, application smoke tests, cleanup, and reporting where practical. Preserve the recovery point tested, database version, test environment, duration, validation results, exceptions, and reviewer.
Automation does not remove the need for periodic operator drills. A person still needs to prove that the runbook is understandable, credentials are obtainable, decisions are assigned, and communications work when the normal path is unavailable.
Turn failures into backup-policy changes
A restore test fails usefully when it reveals a missing extension, stale password, inaccessible key, corrupt artifact, undocumented dependency, inconsistent data, excessive duration, or application regression. Record the cause and change the backup, retention, runbook, or application design.
Do not close the finding because a later manual workaround succeeded. Update the repeatable procedure and run the test again until the recovery objective is met.
Use a recovery-test checklist
- Define RPO, RTO, and business validation criteria.
- Inventory backup methods, versions, keys, accounts, and dependencies.
- Validate the artifact and restore it into isolation.
- Run database consistency and application-level checks.
- Test recent, older, and point-in-time recovery scenarios.
- Measure total recovery time, including validation.
- Preserve evidence and retest every corrected failure.
Prove recovery before the incident
Backup monitoring answers whether data was copied. Database backup testing answers whether the business can use that data again. Recovery confidence comes from repeated restores, measured results, application evidence, and operators who have practiced the work.
If critical software has backups but no recent restore evidence, Eckman Design can help map and test the recovery path before a real failure sets the deadline.
Discussion
0 Comments